Convert PDF tables to Markdown
Turn aligned PDF columns into a GitHub-flavored Markdown table in the browser, and see when a table stays plain lines.
What a PDF table actually is
People ask how to convert PDF tables to Markdown because a paste from a viewer gives you one chopped line per cell, often in the wrong order. The file does not contain a table object the way a spreadsheet does. Each word is a text run with an x and a y. A ruled box is just a drawing. Any converter that emits a GitHub-flavored table is reconstructing that grid from coordinates.
PDFtoMD does that reconstruction in the tab. Detect tables is on by default. You can turn it off, and the choice is stored in this browser under the options already on the converter. Turning it off does not send the file anywhere. The bytes stay in memory and the page runs the same text again without the table pass.
Steps
- Open the PDFtoMD converter and leave Detect tables checked.
- Drop a text-based PDF, or open the field-kit sample linked on this page.
- Read the Markdown source. A recovered table uses pipes and a separator row of dashes.
- If the grid is wrong, uncheck Detect tables. The same file is converted again from memory as ordinary lines.
- Copy the Markdown or download the .md file. The PDF is not uploaded.
Worked example
The sample table.pdf is a one-page letter-size PDF. A 12 point line says “Supply list for the field kit”. Under it, four lines place Item, Qty, and Price at x positions 72, 280, and 420, with Notebook, Pencil, and Whistle on the next lines. A sentence about US dollars sits well below the grid. There are no border lines. This is the Markdown the converter wrote:
# Supply list for the field kit

| Item | Qty | Price |
| --- | --- | --- |
| Notebook | 2 | 12.00 |
| Pencil | 10 | 0.80 |
| Whistle | 1 | 6.50 |

Prices are in US dollars and exclude tax.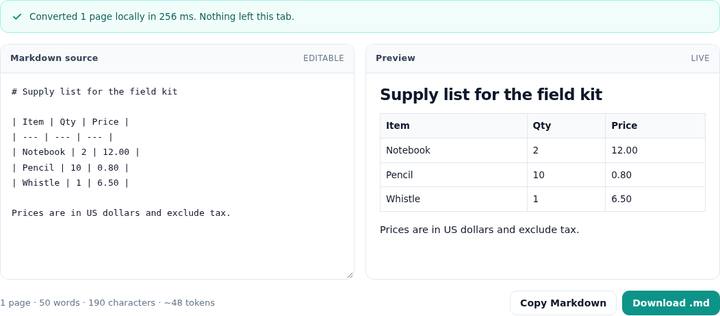
The pipe characters and the | --- | --- | --- | row are the table. The price sentence stayed a paragraph because it has one cell, not three. The title became a level-one heading even though it is the same 12 point size as the cells. It is a short line with no ending punctuation, sitting alone above the grid, so the short-line rule treated it as a heading. That is not font-size detection. The headings guide covers the size rule with a sample that actually changes point size.
How a row becomes cells
Whitespace-only runs are dropped first. PDF.js sometimes emits a space whose width covers the gap between columns, and that fake width would glue Item to Qty. After that, items on one baseline are clustered. A new cell starts when the gap before the next item is wider than the larger of 16 points and 2.2 times the font size. On this sample the jump from about x 72 to x 280, and from the end of Qty to x 420, clears that bar. Notebook, 2, and 12.00 land in three cells.
A table is emitted only when at least two consecutive lines are table candidates, every line has the same cell count of two or more, and each cell’s x lines up with the first row within 14 points. The first of those lines becomes the header row. Pipe characters inside a cell are escaped so a price like “a | b” cannot break the grid. Bullets and numbered lines are not treated as table rows.
A row of short cells is not a two-column article. Column detection demands one wide empty band and at least three long text items on each side. The Qty and Price cells are short, so the field-kit page stays a table instead of being read as a left column and a right column.
What this will not rebuild
Merged cells have no empty slot, so the row’s cell count will not match its neighbors and the block stays lines. A cell that wraps to a second visual line becomes two lines with different shapes, and the pair fails the equal-count test. A header that spans two lines fails the same way. Multi-page tables are not stitched; each page is read, then the pages are concatenated, so a repeated header row can show up again. If the grid is money or a lab sheet you will quote, compare the pipe table to the PDF before you trust a digit.
If you only wanted the words, uncheck Detect tables and leave the field. The converter reruns locally. You should then see “Item Qty Price” style lines, or separate lines, instead of pipes. There is no server fallback and no optical character recognition behind the toggle.
Questions
Does PDF store a real table?
No. A PDF stores positioned text, not rows and cells. PDFtoMD guesses a table only when two or more lines share the same number of aligned cells.
Why did my table stay as separate lines?
The rows did not share a stable column count, a cell wrapped onto a second line, or cells were merged. Uncheck Detect tables if you would rather keep the line-by-line text.
Will a borderless table still convert?
It can. The converter looks at text positions, not ruling lines. Short aligned cells can become a pipe table even when the PDF draws no borders.